AI in Marketing: Testing a Pilot Before Connecting It to Your Systems
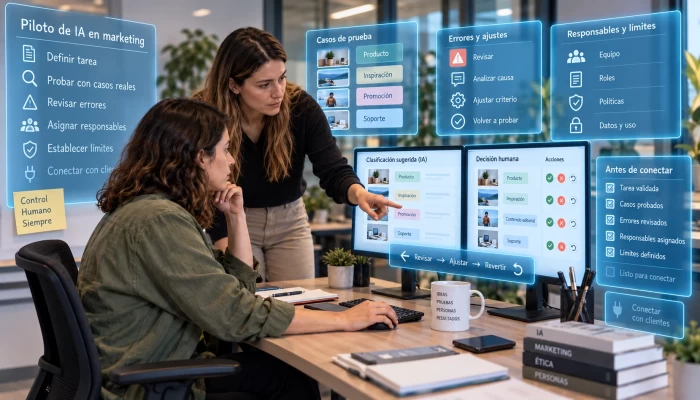
A marketing AI pilot needs a clear task, test cases and officials capable of rectifying or stopping their use. That guide proposes evaluating an aid to classify campaign consultations before connecting with customers. The decision depends on pilot results, rather than an overall promise about technologies.
To choose a task to check the result
The initial task of an agency's proposed example is to propose whether the message corresponds to web design, maintenance or an outpatient question. It does not include answering to the client, changing prices and sending a proposal. The task can be determined by comparing a suggestion with a person's work and monitoring errors before an extension of permits. The pilot should be able to describe itself in a sentence that the care team recognizes and can put to the test. When this diagnosis needs to be put into implementation, Web design, SEO and marketing provides a concrete, measurable path for the next step.
Record who will use the suggestion, what information you need and what decision you have. If an inquiry is ambiguous, select an outstanding review output rather than forcing a category. The test should include messages that mix several services and others that do not explain what a person needs. Those situations serve to figure out what the system will do when they cannot solve their task. Do not have a simple example's success rate as a guarantee that they will conduct any conversation that will come from a future campaign. To expand this point, How a Small Business Can Use Artificial Intelligence Without Overcomplicating Things provides a complementary context within the same path.
The NIST Playbook proposes to select methods and metrics of measurement from the risks identified in the context of use. The Playbook organizes suggestions about governance, identifying the context, measuring and managing the risks of AI. NIST clarifies that its Playbook suits the case of use and does not require following all suggestions as a universal list.
Document of the pilot's context and boundaries
Before installing an assist, describe the current course of consultations: where they come from, who reads them and how they are assigned. It identifies what step they are expected to support and what remains out. To this example, keeping the human assignment allows us to verify the suggestions without sending them automatically to different departments. The computer should be able to check what classification was put forward and what was accepted by the person responsible. If that registration does not exist, it will be difficult to figure out if the problem came up with an interpretation of the message or a later distribution rule.
It also sets up an inventory of information used by the pilot. Do not add complete conversations by default if an authorized and limited text for the test would be sufficient. It agrees with those responsible what data can be used, where they are saved and when they are no longer necessary. That guide proposes questions to review the operation and does not certify that a supplier complies with specific requirements and does not substitute for an organisation's assessment. The test should be conducted with fictitious data or with material authorized for use for that particular purpose.
To create a set of tests that includes faults
Select queries that represent the expected work and write down the response that the computer considers appropriate. To classify services, includes clear requests from a new site, maintenance problems, incomplete messages and non-business consultations. Keep separate examples used to configure the pilot and those reserved to evaluate them. If you only re-test messages that helped to adjust their instructions, the result doesn't explain how they will conduct with different inputs. Save a description of each case so that another person can review the comparison.
Do not reduce the evaluation to a percentage of right categories. Also register the type of error and its operational result: an urgent maintenance request sent to the wrong team may require a different priority to a bad general question. It's a proposal to discuss with care and development, and not a universal scale of risks. It lays down what results require to stop the test and what failure can be corrected during the pilot. Acceptance conditions should be established before monitoring the results to avoid justifiable them only because they appear appropriate.
Keep a person responsible for accepting the suggestion
The pilot interface should allow us to recognize that classification is a suggestion, to see the authorized message and to choose an alternative. Test with the computer if that review adds clarity or creates excessive confidence in automatic output. A button to accept itself does not prove useful monitoring if the person does not have the context and time to evaluate. He propose to note how ambiguous cases are solved and to record why the suggestion is changed. That information helps to figure out patterns that require a pilot's correction.
For this phase, avoid connecting additional actions only because the classification appears to work in some cases. Assign responsible, answer, modify data and publish messages are tasks with different effects. Each extension needs a description and its own tests. Documents who can approve a change and how an assistant will be disabled if a problem appears. In the example, the original consultation tail should continue to be available for care. Retiring the earlier path would have to be a useful action, not an instruction that nobody tested before the launch of the campaign.
To measure the pilot versus work to be improved
Compare results with the current process using the same set of cases and the same definitions. Observe classification errors, inquiries submitted to review, check time and necessary corrections. Please explain how much you describe each measurement and during what period. If the computer needs more time to check out outputs rather than to classify directly, record that result even if the percentage of right categories are high. The decision to continue should consider the complete path and not just a striking response to the tool at a commercial demonstration. Research of the topic provides the context and boundaries of these data.
Save the configuration that each result produced to be able to repeat the test after a change. A titration of instructions, categories or integration can change the observed performance. It defines what cases have to be re-run and preserves the previous faults as part of the check. Do not publish productivity improvements if they have not been measured at the authorized work of the agency. In this guide, the metrics are propose to design an own assessment and the results of a supplier or another organisation do not prove the performance of the specific pilot.
Decide next phase with evidence and conditions
The closure of the pilot should leave a written decision: to continue with limited scope, to correct a condition or to return to the previous process. To relate that decision with established cases and criteria, including outstanding errors. For the example campaign, it may be reasonable to retain the suggestion only for clear consultations and to leave the rest under review. That decision does not mean that the technology will be suitable for any service or that it will have to be incorporated into all CRM modules. The range chosen needs to be commensurate with the available evidence and with the actual monitoring capacity. AI on Websites: What Can Be Automated Today and What Still Requires Human Oversight provides a complementary context within the same path.
Before an extension of the pilot, repeat a controlled interruption: deactivates the suggestion in the testing environment and checks that care can still be received and classified. Also check what the equipment will see when a response lacks or an unrecognised result arrives. Assign a date to review the decision with new authorized cases and a person responsible for monitoring malfunctions. The final recommendation is to preserve an understandable, measurable and reversible path. A approved pilot is a concrete assessment that should be maintained and a permanent authorisation to conduct an automatic conduct with customers without new checks.
What to review in this case
- The pilot defines a single task and keeps decisions out of its reach.
- The data used have an authorized aim and a processing agent.
- Evaluation cases include clear, ambiguous and non-service inputs.
- The terms and conditions of acceptance and detention have been agreed before they have been measured.
- Errors and review time were recorded as a result of the agency's current process.
- The computer can deactivate the suggestion and continue to care for the original tail.
Sources consulted
Editor: Angel G.
Angel G | One Rhino · Web design, SEO and digital marketing.